Unicode code point converter
Turn text into Unicode code points, UTF-8 or UTF-16 bytes, HTML entities and escape sequences, or paste any of those to get the text back. "Show each character" lists the code point and bytes of every character.
Show each character
Runs in your browser. Nothing you type is uploaded.
How to use the converter
- Choose the direction under Convert: Text to Unicode, or Unicode to text.
- Pick a Format: code points (U+), decimal code points, UTF-8, UTF-16 or UTF-32 bytes, JavaScript or JSON escapes, Python escapes, HTML entities, CSS escapes or URL encoding.
- Type or paste in the left box. For escape formats, plain letters and digits stay as they are unless you tick "Escape plain ASCII too".
- Swap direction sends the result back through the other way, which is a quick way to check it.
Code points and encodings
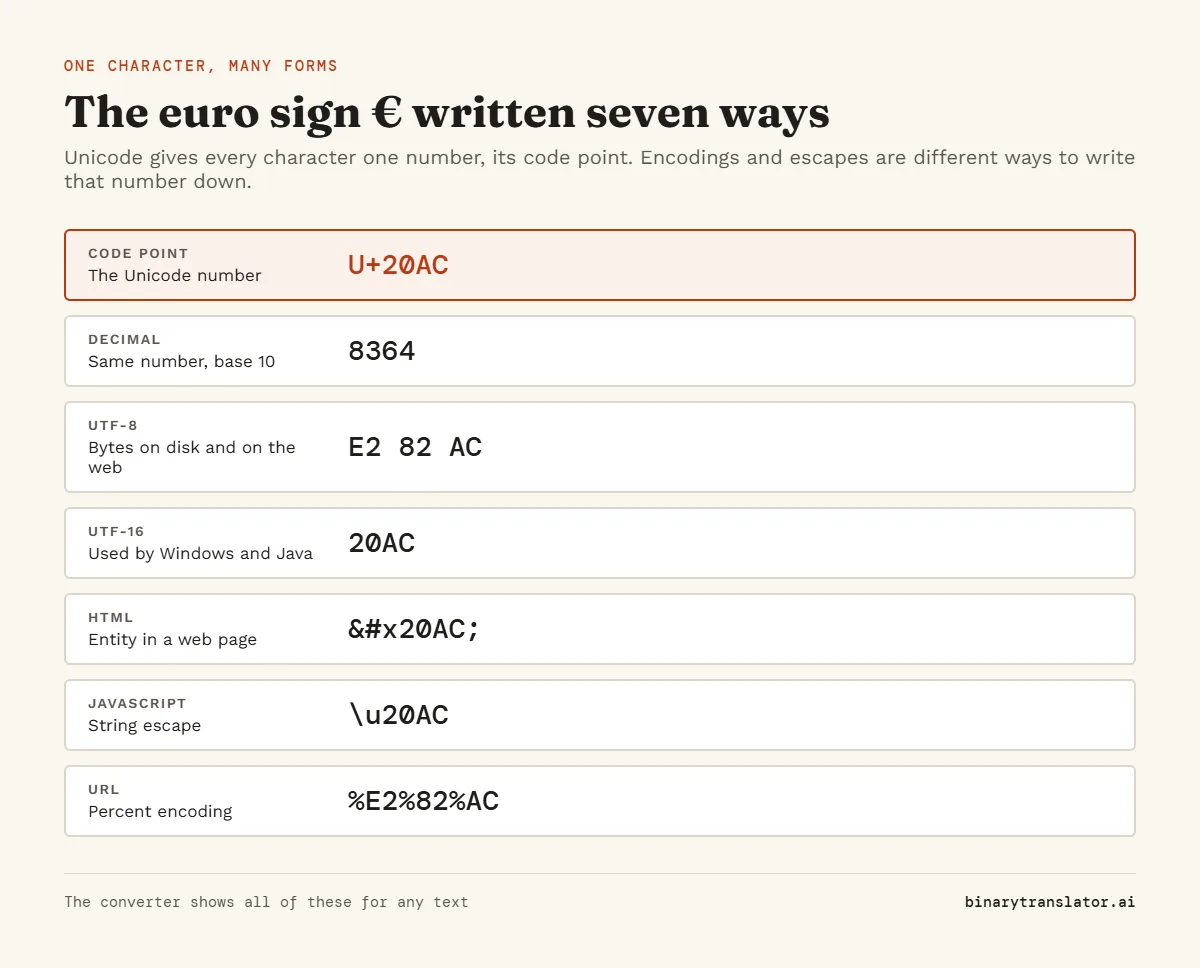
Unicode gives every character a number called a code point, written U+ followed by hex digits: A is U+0041, é is U+00E9 and the euro sign is U+20AC. An encoding decides how that number is stored as bytes. UTF-8, used by about 98% of web pages, stores € as E2 82 AC. UTF-16 stores it as the single unit 20AC. Escapes and entities are ways to write the code point inside source code or HTML.
The formats compared
| Format | é | € | Used in |
|---|---|---|---|
| Code point | U+00E9 | U+20AC | Unicode charts, documentation |
| Decimal | 233 | 8364 | HTML &#…; entities, some databases |
| UTF-8 bytes | C3 A9 | E2 82 AC | Web pages, files, Linux, most APIs |
| UTF-16 | 00E9 | 20AC | Windows, Java, JavaScript strings |
| UTF-32 | 000000E9 | 000020AC | Some internal program formats |
| JavaScript / JSON | \u00E9 | \u20AC | Strings in code and JSON files |
| Python | \xe9 | \u20ac | Python string literals |
| HTML entity | é | € | Web pages and email |
| CSS | \E9 | \20AC | The content property in stylesheets |
| URL encoding | %C3%A9 | %E2%82%AC | Links and form data |
How UTF-8 stores a character
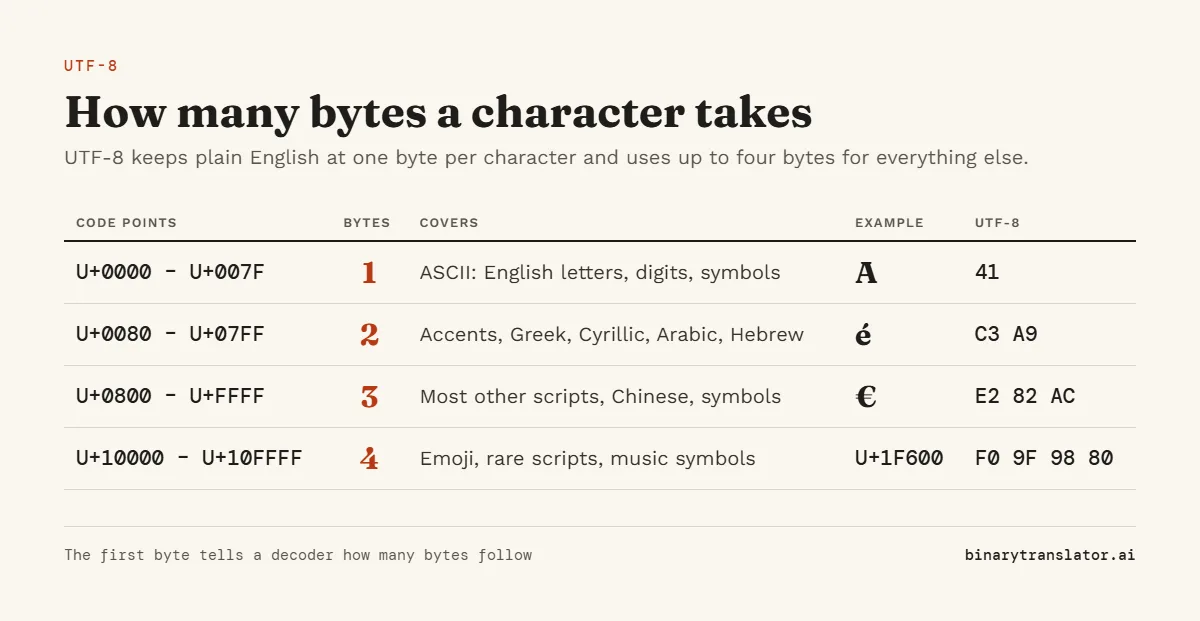
UTF-8 uses the first bits of each byte to say how long the character is. One-byte characters start with 0, two-byte ones with 110, three-byte ones with 1110 and four-byte ones with 11110. Every following byte starts with 10. For é, the code point U+00E9 is 00011101001 in 11 bits. Split into 5 and 6 bits and add the markers: 11000011 10101001, which is C3 A9.
Emoji and surrogate pairs
Code points above U+FFFF, which include most emoji, do not fit in one 16-bit unit. UTF-16 writes them as a surrogate pair, two units from ranges that the Unicode FAQ on surrogates sets aside for this job. 😀 is U+1F600: subtract 10000 (hex) to get F600, then the top 10 bits go into a unit starting at D800 and the bottom 10 bits into one starting at DC00, giving D83D DE00. That is why "😀".length is 2 in JavaScript and why JSON writes the emoji as \uD83D\uDE00. In UTF-8 the same emoji is four bytes, F0 9F 98 80.
Decoding Unicode back to text
Set Convert to "Unicode to text" and paste the codes. The escape formats accept a mix, so a string like caf\u00e9 & crème still decodes. This is handy for reading escaped JSON, fixing é that leaked into exported data, or reading the %XX parts of a URL. Bytes that do not form valid UTF-8 are reported instead of being shown as the replacement character �.
For plain ASCII text, where each character is one byte, the text to hex and text to ASCII converters give the bytes in hex, decimal, binary or octal.
Code point converter or fancy text generator?
Some sites called "Unicode text converters" turn ordinary letters into look-alike symbols such as bold, script or circled letters. Those are real Unicode characters from blocks such as Mathematical Alphanumeric Symbols, which is why they paste into social media. Screen readers often read them letter by letter or skip them, so they are best kept for decoration. This page does not make fancy text. It does the opposite job: it shows the actual code point and bytes of whatever text you give it, including those look-alike letters.
Unicode in Python, JavaScript and HTML
- Python:
hex(ord("é"))returns'0xe9', and"é".encode("utf-8")returnsb'\xc3\xa9'. - JavaScript:
"é".codePointAt(0).toString(16)returns"e9", andencodeURIComponent("é")returns"%C3%A9". - HTML:
éandéboth display é.
The Unicode code charts list every character by block, and RFC 3629 defines UTF-8.
Frequently asked questions
What is a Unicode code point?
The number Unicode assigns to a character, written as U+ and at least four hex digits. A is U+0041 and the euro sign is U+20AC.
Is UTF-8 the same as Unicode?
No. Unicode is the list of characters and their numbers. UTF-8 is one way to store those numbers as bytes; UTF-16 and UTF-32 are others.
How many characters can Unicode hold?
The code space runs from U+0000 to U+10FFFF, which is 1,114,112 positions. More than 150,000 of them have characters assigned.
What is U+0020?
The ordinary space. U+00A0 is the no-break space, which looks the same but stops a line from breaking there.
Why do I see � in my text?
That is U+FFFD, the replacement character. A program shows it when bytes could not be decoded, usually because the text was read with the wrong encoding.
Is my text sent anywhere?
No. All conversions run in your browser.